
Build a Fully Automated AI News Scraper with n8n + Firecrawl
Day 2: Agentic AI
Welcome to Day 2 of Agentic AI Series by Devs Core
_You don’t need a team of writers. You need a system that thinks, filters, and delivers. _
That’s what this AI-powered news scraper does—built with n8n and Firecrawl, ready to automate your daily AI content.
Tired of manually curating content for your AI newsletter? What if your AI tools could read the internet for you, pick out what matters, and deliver it clean and ready to use—every single day?
That’s exactly what we built at Devs Core.
In this blog, we’ll walk you through a powerful, plug-and-play n8n automation template that scrapes AI-focused news daily, filters it using smart prompts, extracts sources, and stores clean content in your S3 bucket. We’ll also break down complex parts like setting up Reddit scraping, using Firecrawl for content parsing, and managing Supabase storage.
Who is this for?
Tech founders and marketers who want to automate content discovery
Writers and creators building newsletters or blogs
Agencies building AI media assets for clients
🧪 What This Template Does
This no-code pipeline does all the heavy lifting for your content curation:
Scrapes news stories from top AI sources (Reddit, TechCrunch, Google News, etc.)
Uses Firecrawl to extract clean article content (markdown + HTML)
Filters non-relevant or duplicate content using an AI agent
Extracts any primary source links mentioned in the article
Uploads final results to your Supabase (S3-compatible) bucket
(I am using superbase s3 bucket for the content storage. You can also use any storage system for this. A simple google drive folder would also work)
🤖 Section 1: How Scraping Works
This system scrapes AI-related content from various sources like:
(As we are interested into AI space, we are focusing on AI contents. You can change that to any topic of your choice. Just update the prompts and the rss feed sources accordingly. You can contact us if you need help!)
RSS feeds from top AI blogs
Subreddits like r/MachineLearning
Google News queries with AI keywords
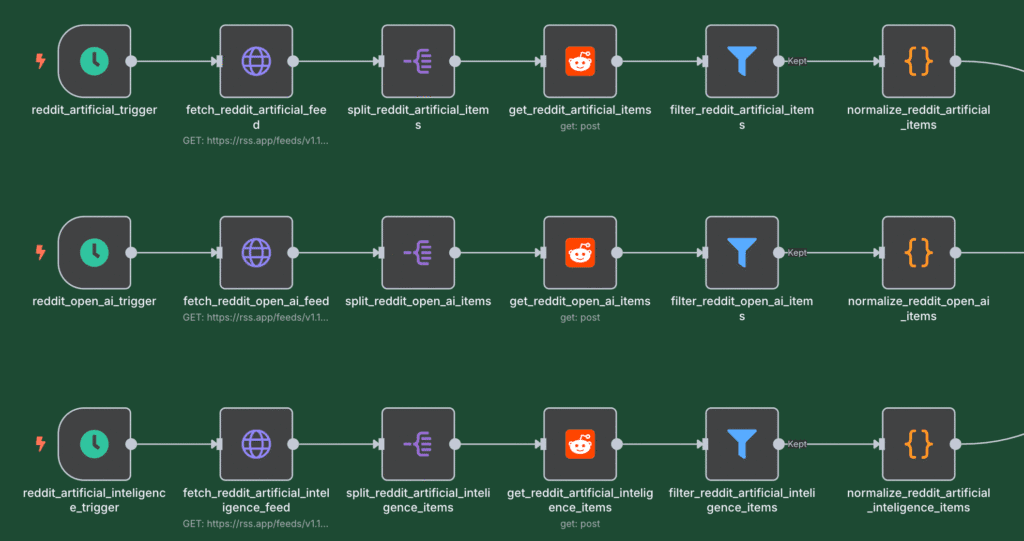
Each source uses its own node setup. For example, Reddit is integrated via a custom webhook or RSS-to-JSON feed. Once stories are pulled in, they pass through:
✅ Filter Logic (Why This Matters)
We use a Filter node to skip any content that already exists in our bucket. This prevents redundant scraping and saves storage + API credits.
⚖️ Set Node (Tagging Logic)
A Set node adds metadata like scrape date, source, and topic. This ensures structured storage and helps during retrieval.
🕹️ Section 2: Using Firecrawl to Extract Clean Content
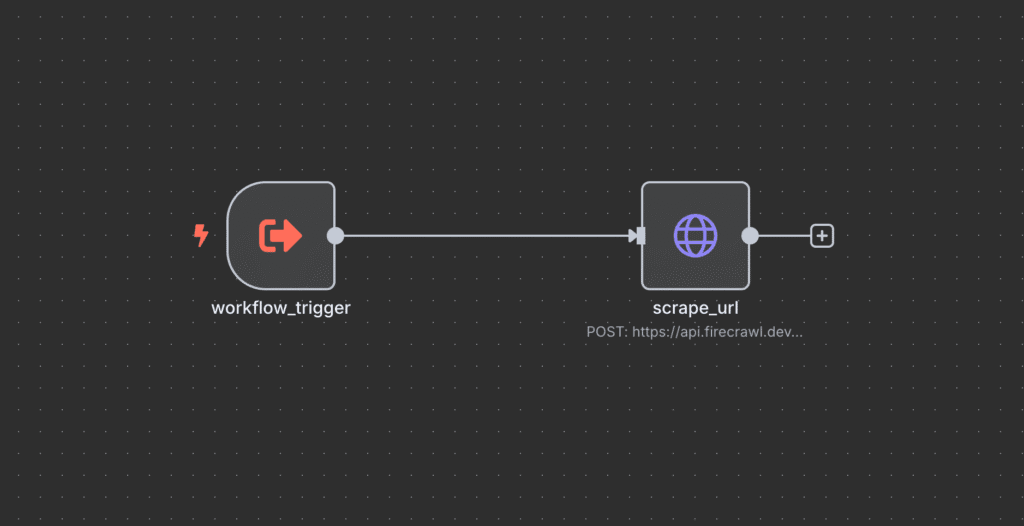
Most websites today have banners, sidebars, and ads. We use Firecrawl, a powerful scraper API that extracts only the main content.
Here’s how it works:
The URL goes into Firecrawl with parameters to return: markdown, HTML, raw text, and image URLs
A custom prompt ensures only useful content is returned (ignores ads, footers, etc.)
Firecrawl returns:
{ "content": "# AI Startup Raises $14M\n...", "main_content_image_urls": ["https://images.domain.com/header.jpg"] }
We call this as a sub-workflow (firecrawl_scrape_agent) to keep the logic modular and reusable.
📊 Section 3: AI Agent for Relevance Filtering
Not every article is newsletter-worthy. So before saving, the content is sent to a custom AI agent (LLM prompt) that:
Checks if the article is **AI-related **(The topic we chose)
Ensures it’s not a job posting, ad, or off-topic
Returns a true or false with reasoning
Sample output:
{ "is_relevant_content": true, "chainOfThought": "Mentions LLM benchmark, GPT-4 comparison, relevant to AI audience." }
This ensures your newsletter content stays laser-focused and trustworthy.
ℹ️ Learn how to write better prompts for relevance filtering in our Agentic AI series.
🔗 Section 4: External Source Extraction
If an article cites a press release, product launch, or research paper, we want that too. Another AI agent:
Scans all external links
Picks the ones relevant to the story
Ignores homepages, nav bars, and unrelated links
This builds contextual depth for your content and allows newsletter readers to explore the original sources.
📂 Section 5: Upload to Supabase Storage (S3)
After filtering, two files are created:
article-name.md
article-name.html
These are uploaded to Supabase storage (S3 compatible) using the Upload node. We organize them by:
ai-news/YYYY-MM-DD/article-slug.md
Note: Supabase requires setup of a public bucket with read access for markdown and HTML viewing.
🎓 Who Can Use This (and How)
This template isn’t just for newsletters. You can use it for:
✉️ AI digest emails (Beehiiv, ConvertKit, Mailchimp)
📃 Company AI blog automation
🌐 SEO-focused content ingestion for your site
🖊️ Social media post generation
📊 Competitive monitoring in specific domains (e.g., FinTech, Healthcare AI)
Want to use this template for sustainability tech or marketing? Just change the input sources and keyword filters.
✨ Setup Guide: Step-by-Step
🧰 How to Set Up Your Reddit RSS Feed
Reddit doesn’t provide RSS for every subreddit by default. Here’s how to generate one:
Visit the subreddit you want (e.g., https://www.reddit.com/r/MachineLearning)
Add .rss to the end: https://www.reddit.com/r/MachineLearning.rss
If using multiple sources, use rss.app to combine and convert feeds to JSON.
Add that URL to your n8n HTTP Request or RSS Feed Read node.
🧠 How to Set Up Reddit API Access (For Advanced Features)
If you want to use the full Reddit API—such as reading post details, saving posts, posting comments, or automating subreddit interactions—you need to register an app:
Visit: https://ssl.reddit.com/prefs/apps/
Scroll to the bottom and click “Create App” or “Create Another App”
Fill in:
App name (e.g., “n8n Reddit Agent”)
App type: Script
Redirect URI: http://localhost:3000 (You can see the redirect URI in your n8n node)
Once created, you’ll get:
client_id (under the app name)
client_secret
In n8n, go to Credentials > Reddit OAuth2 API and enter:
Client ID
Client Secret
Username & Password
Auth URL: https://www.reddit.com/api/v1/authorize
Token URL: https://www.reddit.com/api/v1/access_token
Once configured, you can use the Reddit node to:
Read subreddit posts
Filter by upvotes or time
Save or comment on posts
Crosspost or monitor discussions
🧩 This is optional unless you plan to interact directly with Reddit content or use personalized filters.
Add that URL to your n8n HTTP Request or RSS Feed Read node.
🔐 You do not need Reddit credentials unless you’re using the Reddit API for voting or post metadata.
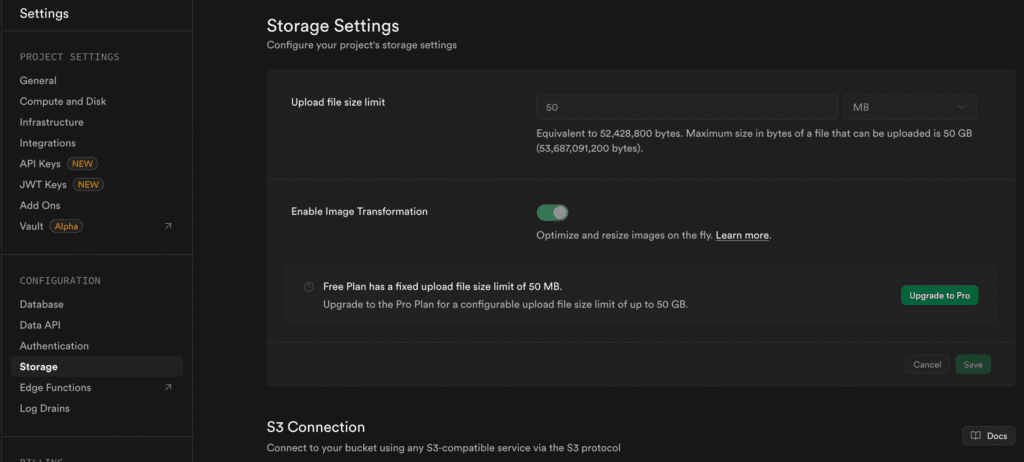
🗃️ How to Set Up Your Supabase S3 Bucket
Supabase offers S3-compatible object storage. To configure it:
Go to your Supabase project dashboard.
Click on Storage > Create a new bucket.
Name it: ai-news
Set privacy to Public if you want to access files via URL.
Click on your bucket > Configuration to find bucket URL.
In n8n, use the S3 Upload node with these credentials:
Access Key (from Supabase > Project Settings > API)
Secret Key
Endpoint: https://<your-project-ref>.supabase.co/storage/v1/s3
Region: Leave empty or use us-east-1
🧪 Test with a dummy markdown file first to verify access.
✨ Final Words
This isn’t just a template. It’s a foundation for your content engine. Whether you’re scaling a newsletter, SEO blog, or LinkedIn strategy, this tool gives you consistency, speed, and relevance.
Want to automate further? In our next blog, we’ll show how to:
Group articles with AI
Write summaries and intros
Format a publish-ready newsletter
📢 Subscribe to the Devs Core AI Automation Series
✅ Download AI News Scraper n8n Template
We believe in building software that stands the test of time. With this automation, so can your content.
WE ARE YOUR TECH PARTNER
Let’s Build Your
Startup Software
Ready to launch a scalable, AI-powered product? We build sustainable custom solutions you can grow with.
				[

								Contact Us

				](https://devs-core.com/contact-devs-core/)